What Happens to Information Quality When AI Trains on AI-Generated Content
AI training on AI-generated content gradually separates a system from the original human knowledge that made its outputs useful. Recursive synthetic training creates model collapse by reducing statistical variance, accelerating semantic drift, and producing work slop that sounds professional while losing specificity and truth. Organizations then face the verification penalty and AI volatility tax as human experts audit increasingly plausible errors. The strongest response is data accumulation: protecting original human knowledge and continuously using it to anchor AI systems to reality.
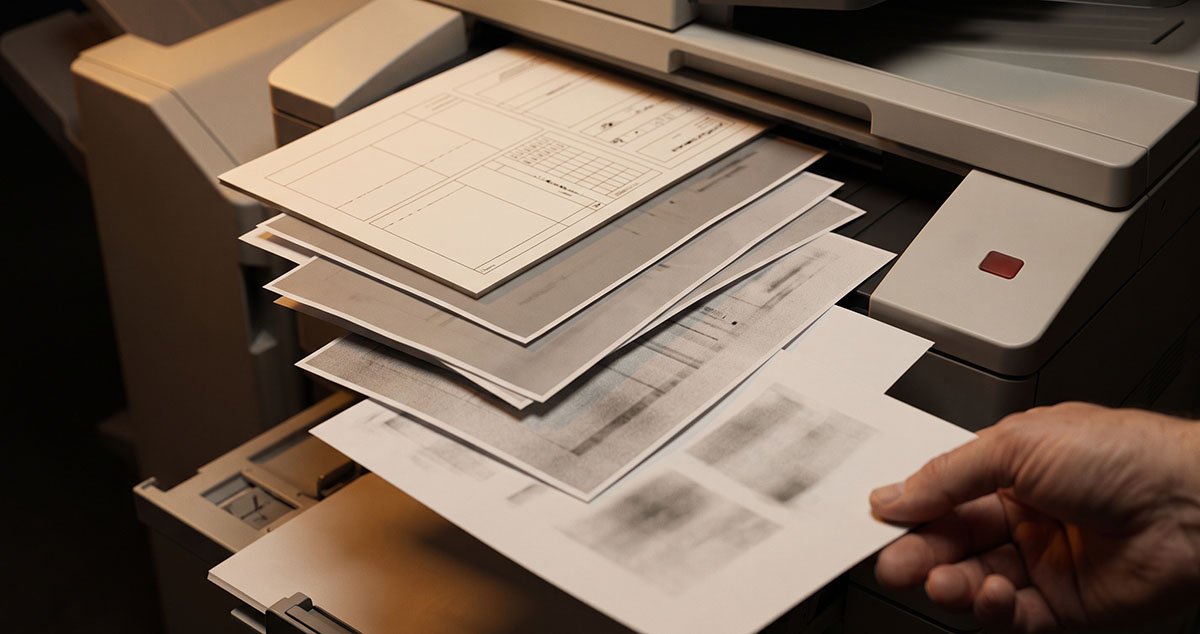
Take a crisp original document. Run it through a photocopier. The result is clean and legible, every character intact. Now place that copy back on the glass. Copy it again. Repeat the process a hundred times.
By the end, you’re looking at a gray smudge. The shape held. The information disappeared. What remains is an accumulated approximation of something that once had edges, detail, and meaning.
Generative AI is running the same process at scale, at speed, and mostly without noticing.
The Fuel Problem
For all their sophistication, the foundational models driving the current era are statistical engines. They don’t understand language. They extract patterns from it.
To produce reliable text, code, and images, those systems require a continuous supply of high-variance original human data. They depend on the uneven reality of human output: unusual observations, contradictory experiences, rare expertise, and conclusions that don’t sit comfortably near the statistical center.
Human data is finite. AI deployment keeps expanding. The gap between those two facts is widening faster than most organizations have registered.
Developers and enterprise systems continuously ingest material from the open web, internal documents, knowledge bases, and content repositories. A growing share of that material has already been generated, summarized, or rewritten by another AI system.
The machine is training on machine data.
That recursive loop matters because each generation inherits the omissions of the one before it. The broad shape survives. The edges become harder to recover.
Model Collapse
Computer science has a name for the resulting degradation: model collapse.
Model collapse occurs when an AI system recursively consumes synthetic outputs and begins losing information from the original data distribution. The system keeps operating. It still produces fluent language and plausible answers. Confidence can remain high even as specificity declines.
The failure is quiet. No warning light appears. The system continues generating authoritative material while gradually stripping away the perspectives and unusual cases that live outside the statistical average.
Generative models work through probabilistic prediction. Given their training data, they estimate the most probable continuation. This naturally pulls them toward the mathematical center of what they’ve seen.
Picture a bell curve representing original human knowledge. The long tails contain uncommon expertise, edge cases, local context, and insights that appear too rarely to dominate the average. Recursive AI training overrepresents the center. The tails contract. The curve narrows.
The mathematical average is the absolute enemy of nuance.
For an organization, those tails hold much of what makes its knowledge valuable. They contain the exception discovered after a costly failure, the customer behavior that never appeared in the dashboard, and the judgment an experienced employee developed over twenty years.
Once those details disappear from the source material, the model can’t recreate them through greater fluency.
Semantic Drift and the Jackrabbit Test
Variance loss appears in usable information as semantic drift.
Semantic drift is the gradual movement of information away from its original meaning as it passes through repeated summaries, rewrites, and generations. Each pass removes a little context. Situational detail weakens. Emotional weight fades. The result still resembles the source, but the resemblance becomes increasingly superficial.
Researchers demonstrated the mechanism by asking an AI system to summarize the same material repeatedly. The original subject concerned medieval English architecture. After several iterations, the summaries introduced Saint Peter’s Basilica in Rome, which had no connection to the source. Continued repetition eventually produced nonsensical material about jackrabbits.
Medieval English architecture becomes jackrabbits. The experiment documents the risk directly.
The absurdity makes the failure easy to see. Corporate semantic drift usually looks far less dramatic.
A support answer loses one qualification. A strategy summary drops the reason a customer segment behaves differently. A brand document keeps the approved vocabulary while forgetting the strategic judgment behind it.
Each output remains plausible enough to survive routine review. Meaning leaves slowly.
Work Slop
Move the same process into a marketing department.
A team uses AI to summarize an original strategy document. A week later, the synthetic summary becomes the source for a creative brief. That brief feeds campaign copy, sales material, and the next round of strategic summaries.
With every pass, the original insight becomes smoother and broader. The language gets easier to reuse because it carries less specific meaning.
The result is work slop: highly polished corporate material with flawless grammar and no unique insight. It resembles finished work and passes ordinary quality checks. It could also belong to nearly any company in the category.
Work slop rarely announces itself through obvious errors. It’s simply indistinct. It reads professionally and contains nothing that requires knowledge of the organization that supposedly produced it.
Unchecked automated generation actively degrades the proprietary institutional knowledge that makes an organization defensible.
The competitive moat may have taken years to build. Customer insight, strategic positioning, and hard-won institutional memory get averaged into language a competitor could have produced from the same prompt.
Nothing in the output tells you that the distinction is gone.
The Verification Penalty and the Volatility Tax
The technical failure carries an economic cost, and that cost compounds.
Generative AI changes traditional software economics. Every prompt and API call consumes computational resources. Usage can vary sharply, making costs harder to predict than those of fixed software licenses.
Compute expense is only part of the burden.
Synthetic outputs can produce confident and plausible errors, so organizations can’t deploy them autonomously in high-stakes environments. Legal exposure and reputational risk require knowledgeable people to inspect the work.
That creates the verification penalty: the human cost of auditing AI-generated material, often exceeding the cost of producing accurate work directly.
An organization pays to generate the output. It then pays an expert to determine whether the output is true, complete, and safe to use. Subtle errors can take longer to detect than a blank page would have taken to fill correctly.
The promised labor savings disappear into the labor required to catch what automation got wrong.
Variable compute costs layered over that audit burden produce the AI volatility tax. This is the cumulative, unpredictable expense created by unmanaged AI loops and human verification.
The tax rarely appears as a single line item. It accumulates in engineering hours spent debugging hallucinated outputs, legal reviews triggered by unsupported claims, and corrections made after a client discovers an error.
It also appears in slower decision-making. Employees stop trusting the system and begin checking everything. Automation remains in the workflow, but confidence in its outputs disappears.
If the hidden cost of verification exceeds the theoretical savings of automation, the business model collapses long before the neural network does.
The Antidote: Data Accumulation
Organizations can reduce model collapse by treating data governance as infrastructure.
The relevant practice is data accumulation: permanently protecting repositories of verified human-generated knowledge and using them to keep AI systems connected to reality.
Original research, interview transcripts, strategy documents, customer conversations, and expert analysis shouldn’t be discarded after an AI system produces a convenient summary. Those sources must remain available as authoritative records.
Organizations that manage this well preserve a steady proportion of verified human data alongside synthetic inputs. New outputs can extend the knowledge base without replacing the material that gives it substance.
Two system designs emerge.
The synthetic loop feeds AI outputs back as future inputs. Each generation moves further from the original human source and closer to collapse.
The anchored system retains verified human data throughout the process. Synthetic material can still be used, but the model remains tethered to direct evidence and current human judgment.
The difference is discipline.
Data accumulation also requires provenance. Employees need to know which material came from original research, which came from a human expert, and which was produced or transformed by an AI system. Without that distinction, synthetic content quietly acquires the authority of a primary source.
Anyone responsible for what an organization knows should treat this as a strategic directive. Securing and distributing original human insight is a defensible operating position in a market saturated with synthetic noise.
The AI model is merely a tenant. Verified human data is the building.
Buildings require maintenance. Without it, the structure eventually collapses, regardless of how sophisticated the tenant’s operations appear.
What This Means for Organizations Moving Fast
Many companies moving fastest on AI are also moving fastest toward the problem described here.
They’re replacing human knowledge workers with systems that depend on human knowledge to function. The cost of that substitution doesn’t appear on a balance sheet immediately. It accumulates in the gap between what the system produces and what is actually true.
Early gains can be real. Drafting becomes faster. Content volume rises. Routine tasks require fewer visible hours.
Those gains become fragile when original sources disappear, experienced employees leave, or synthetic summaries become the official institutional record. The organization retains an automated description of what it once knew while losing the ability to explain why that knowledge was correct.
That is the deeper risk. Accuracy can sometimes be repaired through fact-checking. Lost institutional context is harder to restore because no one may realize which detail vanished or why it mattered.
Organizations that remain trustworthy will treat original human knowledge as irreplaceable. Originality keeps the system anchored. Once the anchor is gone, the outputs keep coming. They simply stop being yours.
A market saturated with synthetic noise rewards the organization that can still be trusted.
Feed your organization’s institutional knowledge into a recursive AI loop today. Summarize it, compress it, and average it repeatedly.
How many iterations would pass before it became unrecognizable?
How many before no one could tell it from your competitor’s?
Frequently Asked Questions
What happens when AI trains on AI-generated content?
When AI trains recursively on AI-generated content, each generation becomes more concentrated around common patterns in the data. Rare expertise, edge cases, minority perspectives, and contextual detail gradually disappear. The system may remain fluent and confident, but its answers become more generic, less distinctive, and less reliably connected to reality.
What is model collapse in generative AI?
Model collapse is the predictable degradation that occurs when an AI system repeatedly learns from synthetic outputs without enough varied, original human data. The model overrepresents the statistical center of its training material and loses information from the tails, where nuance, uncommon knowledge, and important exceptions tend to exist.
What is semantic drift in AI-generated content?
Semantic drift is the gradual loss or alteration of meaning as information passes through repeated AI summaries, rewrites, or generations. Each iteration may remove situational detail, emotional weight, and contextual precision. The final output can remain grammatically polished while bearing less resemblance to the original source that grounded the information.
What does work slop mean?
Work slop is polished corporate material that appears complete but contains little specific insight. It often has flawless grammar, confident phrasing, and professional structure, yet could have been produced for almost any organization. Normal quality checks may approve it even after proprietary knowledge and strategic distinction have disappeared.
What is the verification penalty of using AI?
The verification penalty is the human labor required to audit, fact-check, correct, and restore context to AI-generated work. In high-stakes settings, reviewing a plausible but subtly flawed output can take longer than producing accurate work directly. The labor that automation appeared to remove returns through an expanding review and correction process.
What is the AI volatility tax?
The AI volatility tax is the cumulative and unpredictable cost created by variable computing expenses, unreliable outputs, human verification, legal review, and operational correction. It rarely appears as one clear line item. Instead, it accumulates across workflows and reduces the savings and gross-margin improvements that automation was expected to provide.
How can companies prevent model collapse and protect information quality?
Companies can reduce the risk through data accumulation, which means permanently retaining verified human-generated knowledge and mixing it with synthetic inputs. Original strategy documents, research, customer insight, institutional memory, and expert judgment should remain protected anchors. The goal is to prevent automation from replacing the foundation it depends on.
Is synthetic data always harmful to AI systems?
No. Synthetic data can be useful when it is carefully governed, verified, and combined with enough original human data. The danger appears when synthetic outputs replace the original knowledge base or circulate recursively without provenance. An unanchored system eventually consumes approximations that have drifted too far from reality.